 推論系統
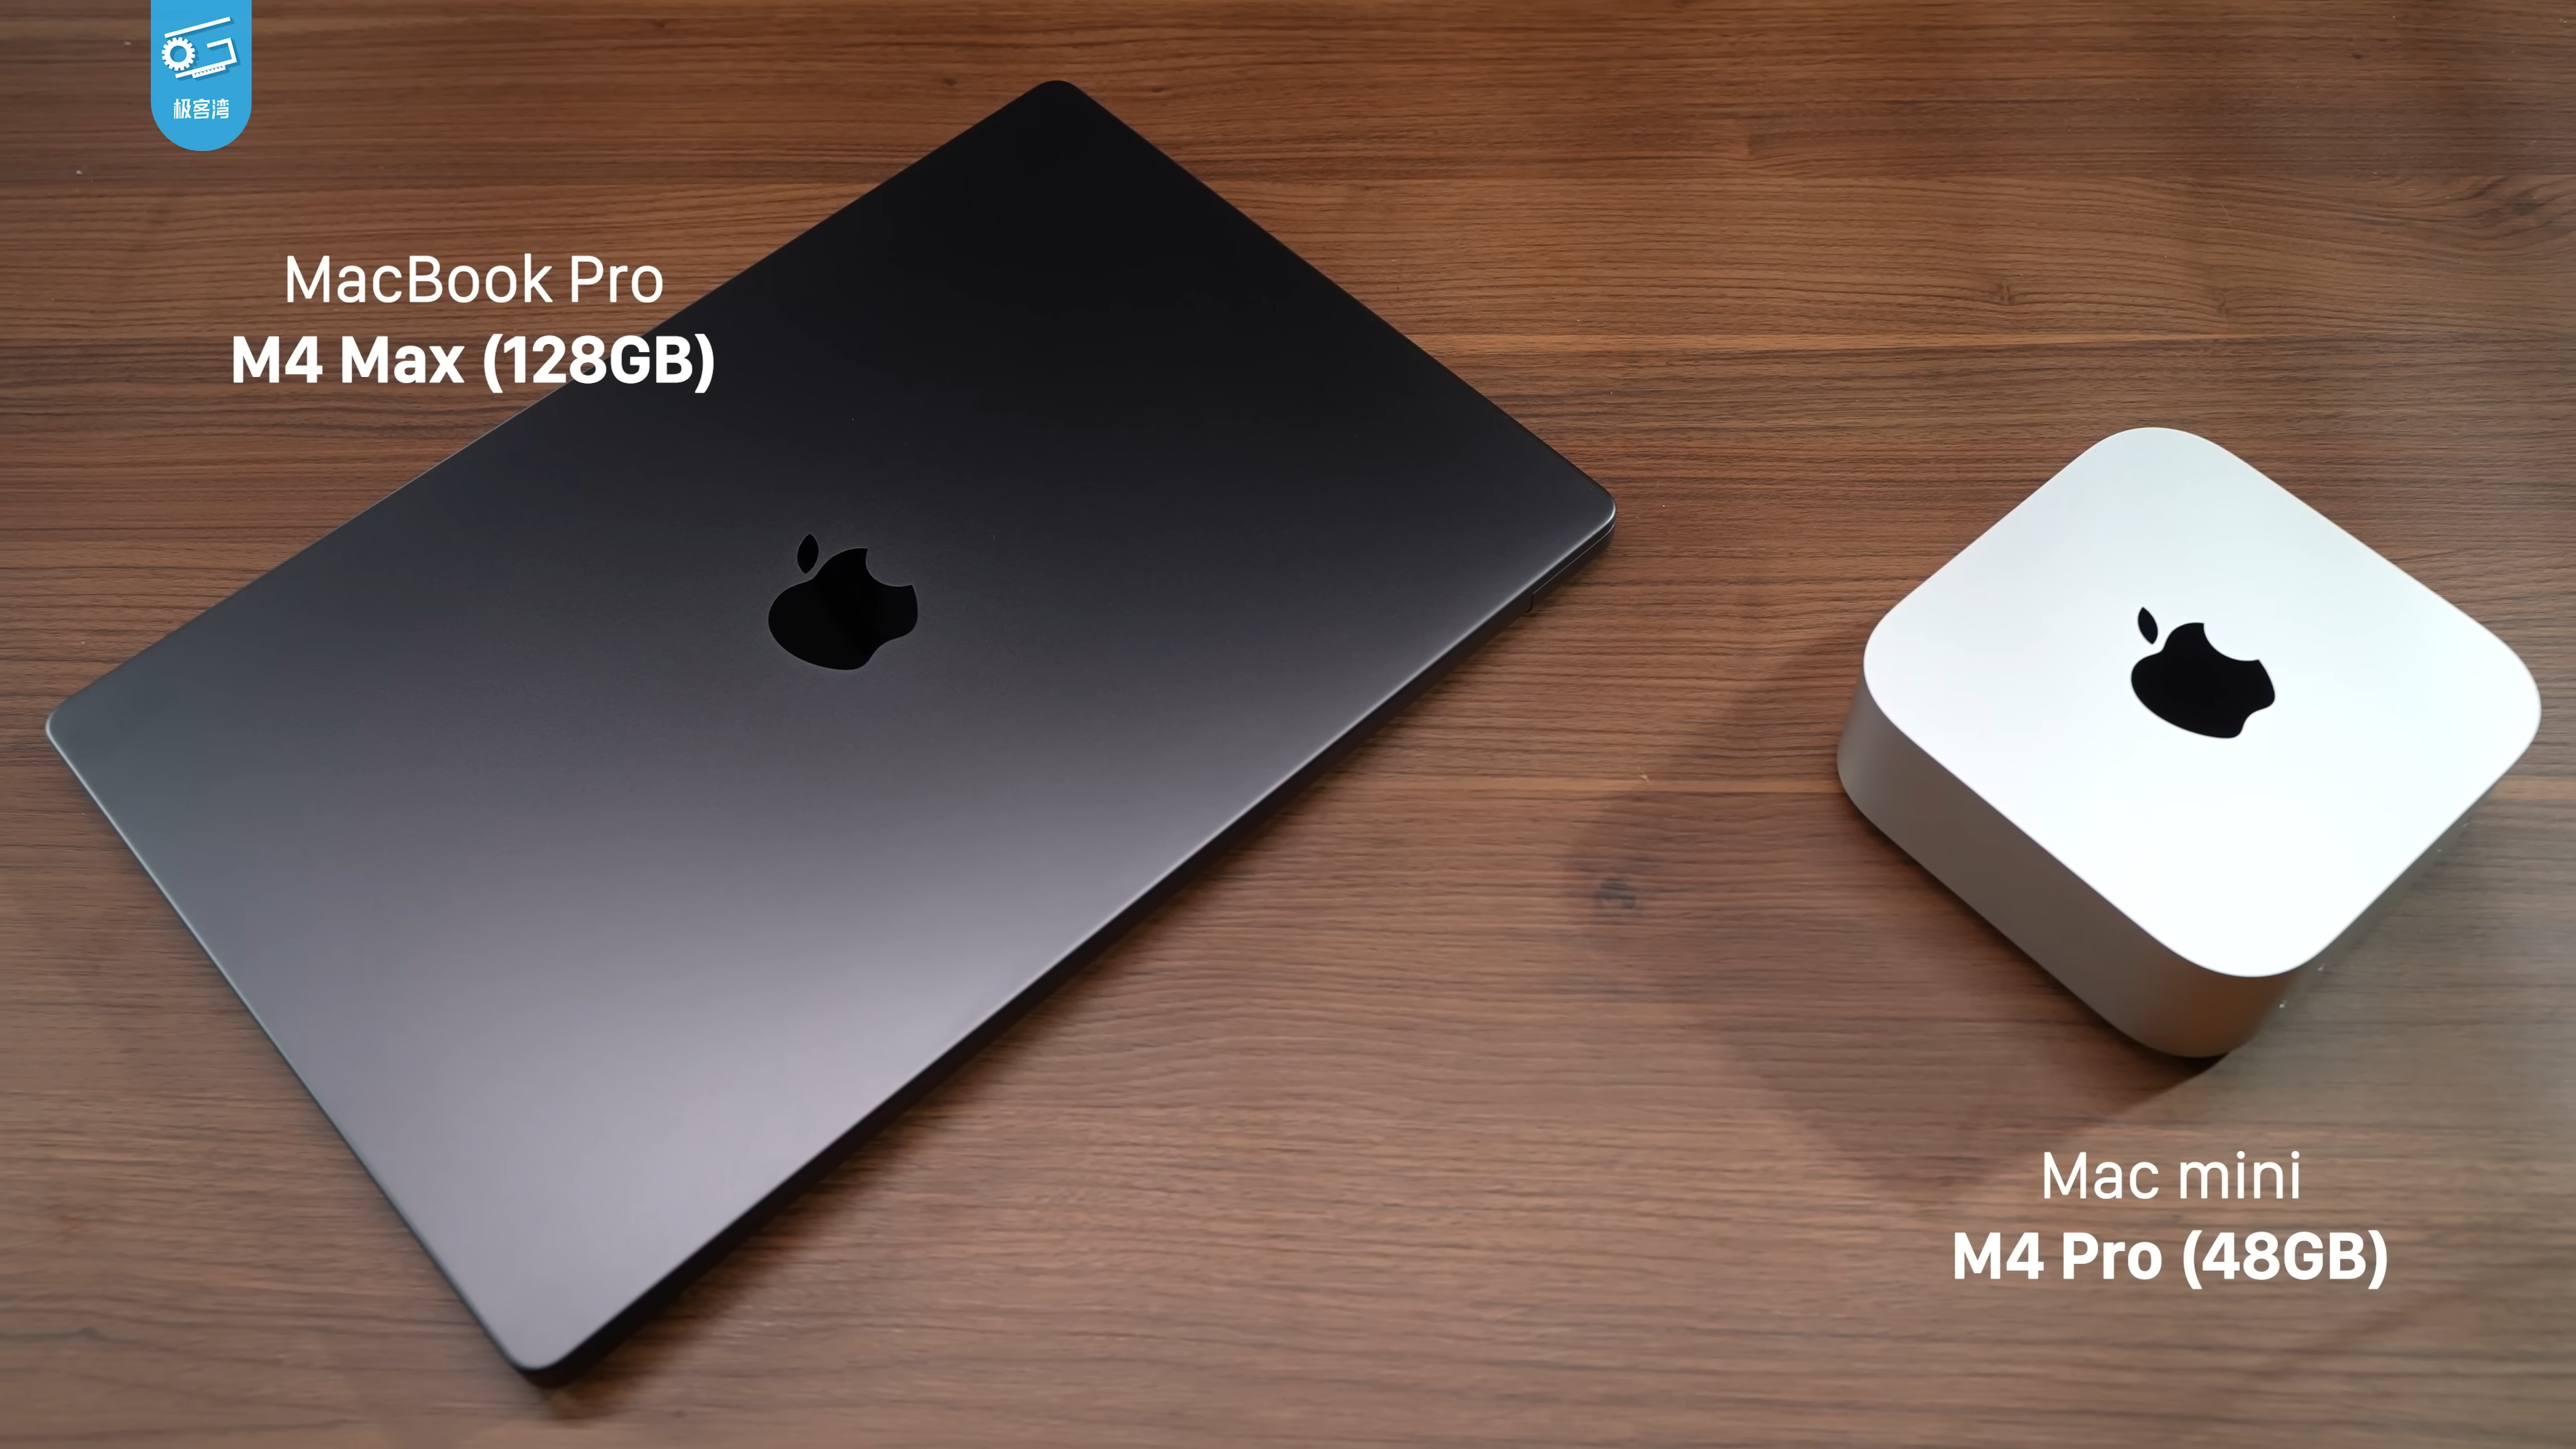
Local LLM Testing on M4 Max: Faster Decoding Than GB10, but Full Responses Remain Constrained by Prefill
A new round of similarly priced local AI testing shows that the M4 Max, with 546GB/s of unified memory bandwidth, leads the GB10 and Strix Halo in per-token decoding across three quantized models. The GB10 still has the advantage in prompt prefill and overall energy efficiency, demonstrating that tokens/s alone can misrepresent actual response times.