AI 安全

模型安全、資安、隱私、供應鏈、紅隊與防護。

最新模型

Adding Compatible Adjectives Still Causes SAEs to Lose 20% to 60% of Activated Features, Challenging the “Bag of Features” Intuition

A Heidelberg University study finds that although individual latents in sparse autoencoders may be interpretable, the full set of activated latents does not map reliably onto human concepts. Simply adding a compatible adjective before a noun can make 20% to 60% of the original activation set disappear, limiting the reliability of interpreting model states through set overlap.

最新模型

Muse Glimmer 30B Brings Multimodal Agents to a Single GPU With 17GB Quantized Weights and a DFlash Draft Model

Meta has released the Muse Glimmer 30B weights, vision encoder, and DFlash draft model. The 17GB version can run text, image, and speculative decoding workloads simultaneously within 24GB of VRAM. Meta measured an average of 233.4 tokens/s on an RTX 5090, but safety evaluations and deployment details show that the model still requires external safeguards and a newer runtime.

最新模型

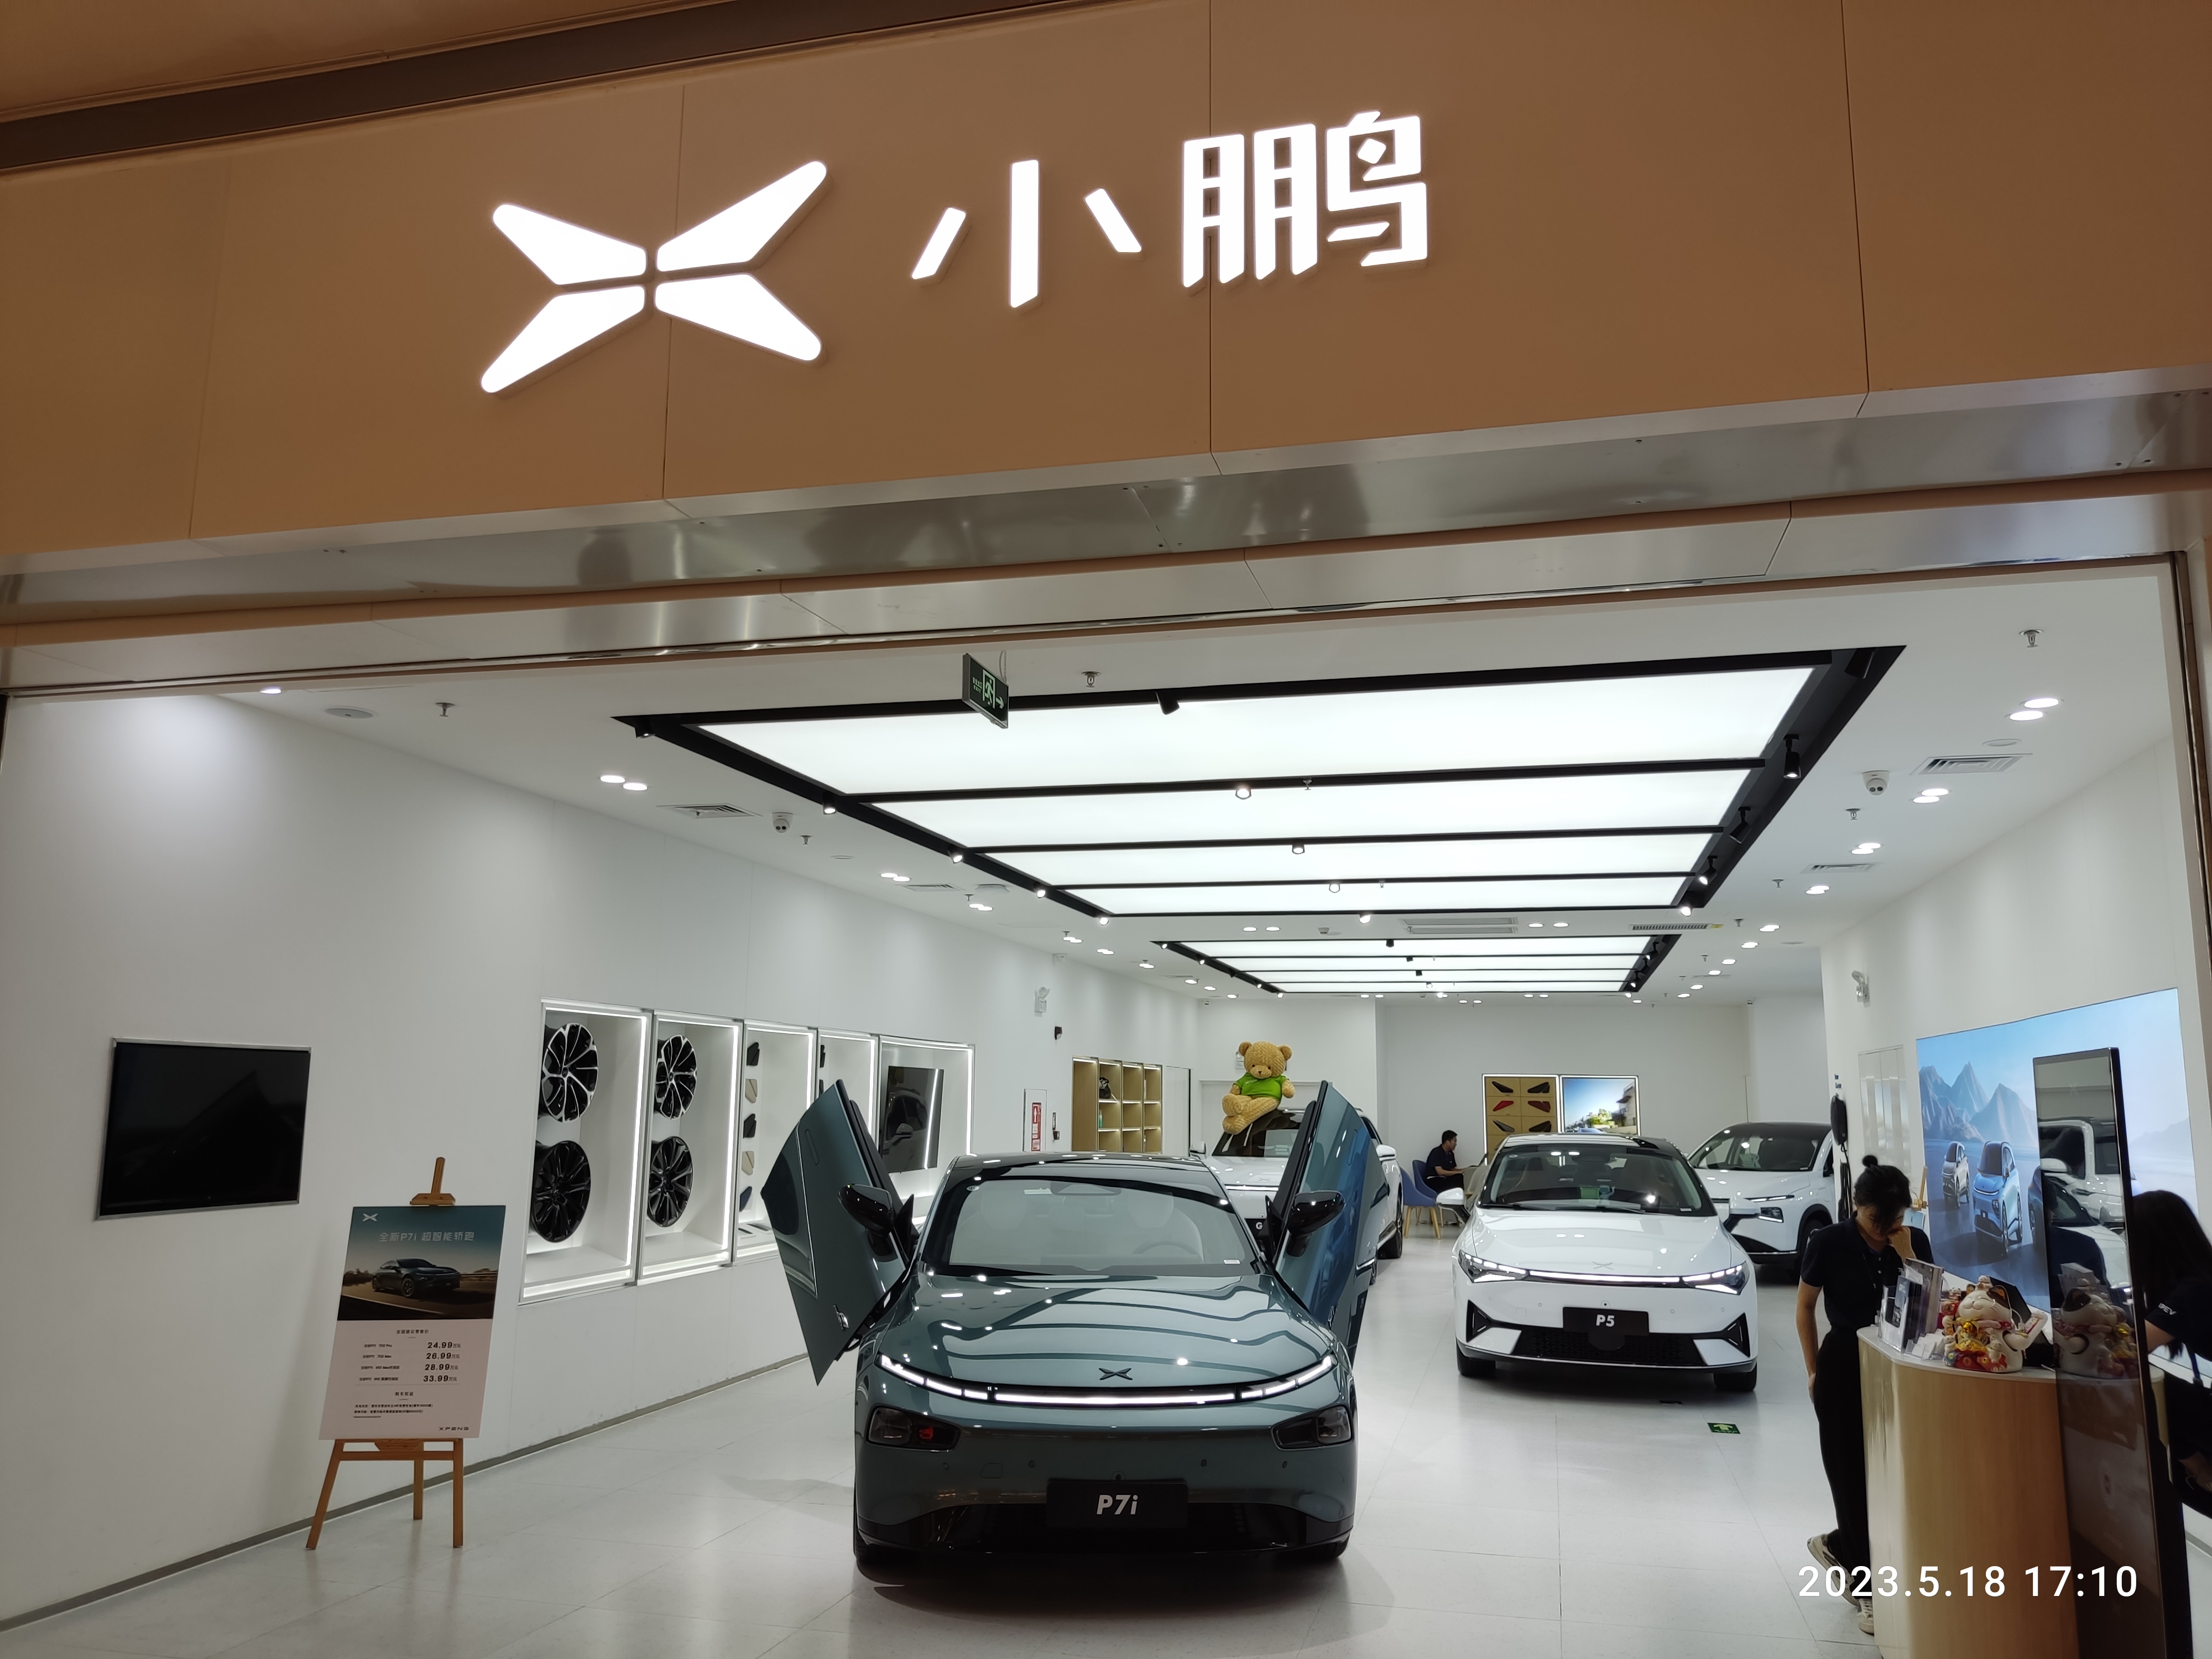
XCoT-VLA Compresses Autonomous-Driving Reasoning into 2–6 Action Tokens, with Interface Latency as Low as 38.6 ms on H100

XPeng introduces XCoT-VLA, replacing dozens of natural-language reasoning tokens with a limited set of semantic action tokens, then using flow matching to generate continuous trajectories. Open-loop tests show lower lateral error, but no closed-loop safety evaluation has been reported, and the latency figures do not cover the full in-vehicle hardware and software stack.

AI 安全

REDAgentBench Recalculates Agent Attack Rates Using Final Service States, Finding Text Trajectories Miss Up to 11.72 Percentage Points

REDAgentBench executed 1,661 attack cases across sandboxed workspace, email, browser, banking, and external file services, rather than judging harm solely from an agent’s response. When the same runs were scored using service receipts and final states, the attack success rates of all six models were 7.73 to 11.72 percentage points higher than with trajectory-only scoring.

最新模型

Universal Activation Bus Shares SAEs and Probes Across Models with a Single Set of Adapters

Universal Activation Bus aligns the intermediate representations of five language models into a fixed 3,072-dimensional space, requiring new models to train only their own linear encoder and decoder. In experiments, models could reuse the same probes, sparse autoencoder, and natural-language explainer, although representation reconstruction for wider models remained noticeably distorted.