最新模型

新模型、開放權重、多模態、語音、影像與模型架構。

訓練基礎設施

Rollplex Fits VLM Reinforcement Learning Prefix Computation into Rollout Idle Time, Accelerating Training by up to 1.30× on 32 H800 GPUs

Rollplex executes video encoding and prompt prefill for the reference model and training actor early, during autoregressive decoding, while preserving synchronous on-policy semantics. The system uses CUDA VMM to manage memory across stages and enables training and inference processes with different tensor-parallel configurations to share compatible weights.

最新模型

Intern-S2-Mobius Shares FFN Memory Globally, With the 35B Model Reporting Nearly 4× End-to-End Inference Acceleration

Intern-S2-Mobius separates the knowledge storage and attention-based reasoning traditionally tied to each Transformer layer, allowing multiple Reasoners to repeatedly query the same global Memory. The open weights can be loaded with LMDeploy, vLLM, or Transformers, but the nearly 4× acceleration remains a result from the official evaluation under specific conditions.

最新模型

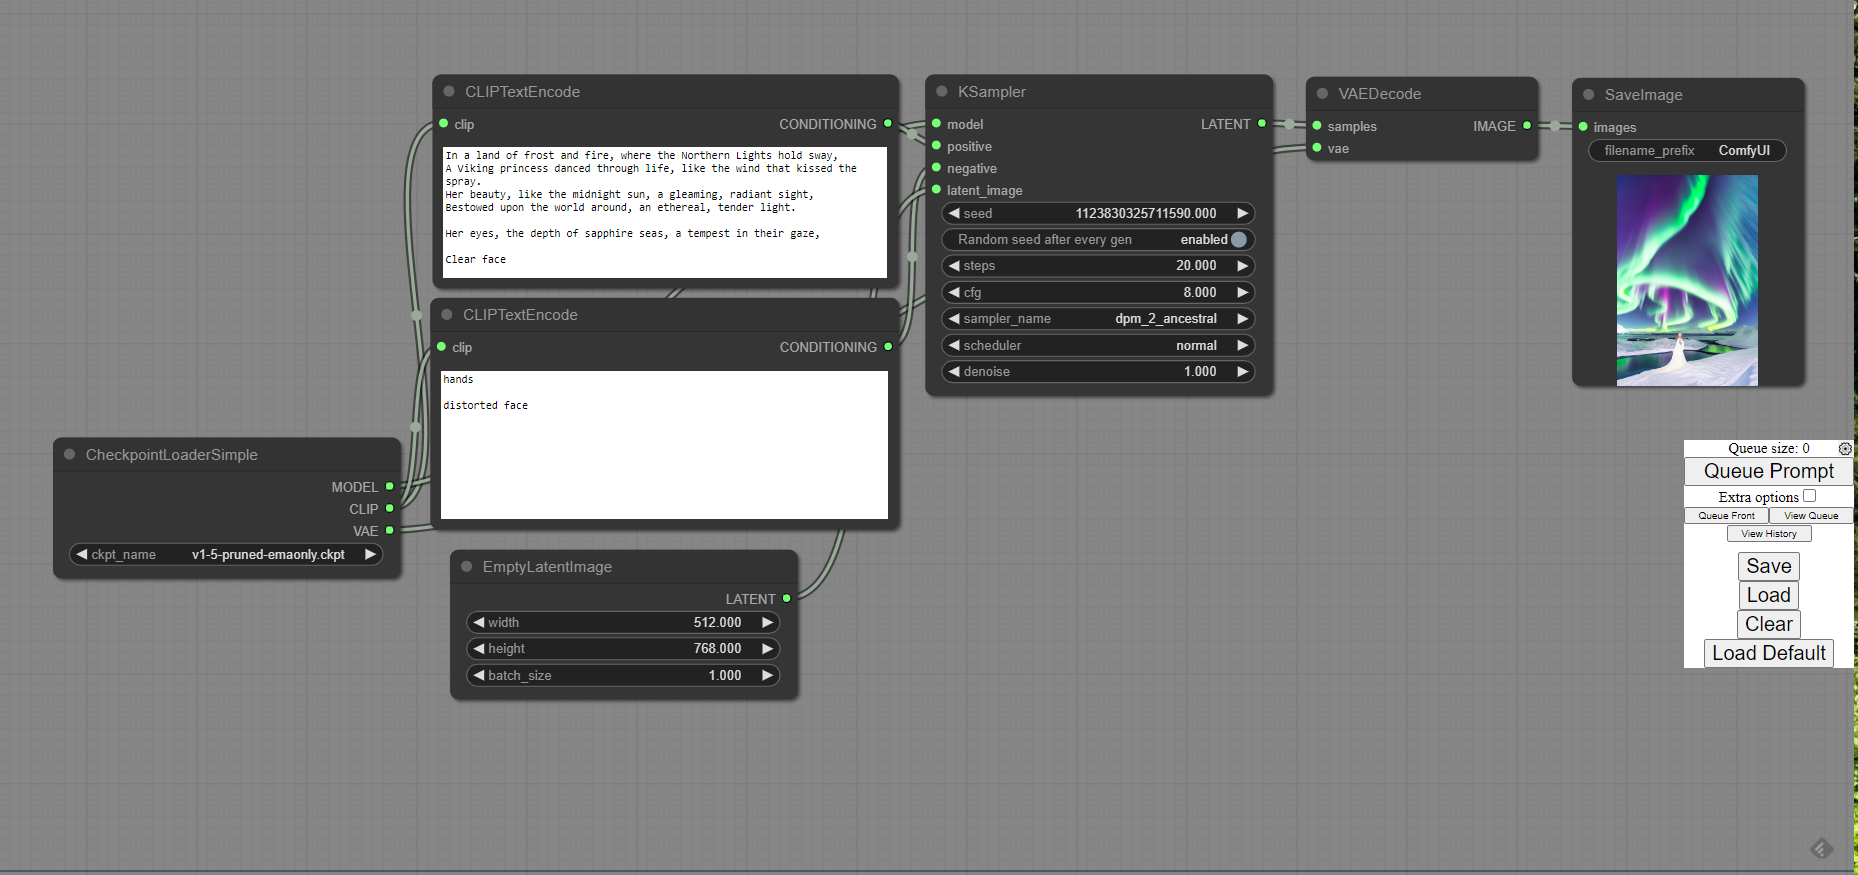
Community Turns MiniMax H3 into an Image Editor with a Single-Frame VAE, Exposing ComfyUI’s Five-Frame Minimum as a Compatibility Gap

The community has trained a 5.21GB single-frame VAE for the MiniMax H3 video model, allowing reference-to-video pipelines to generate just one frame for tasks such as virtual try-on, pose editing, and viewpoint transformation. The approach demonstrates how a video model can be repurposed as an image editor, but it currently depends on unofficial weights, specific workflows, and ComfyUI single-frame support that has yet to be fully implemented.

最新模型

Qwen3.8-27B Delivers a Native 262K Context Window with a Hybrid Linear/Full-Attention Architecture While Retaining Multi-Step MTP

Qwen has released the weights for Qwen3.8-27B, using a 64-layer hybrid Gated DeltaNet/Gated Attention architecture to reduce long-context costs while providing native visual understanding and adjustable reasoning depth. Official agent benchmarks show substantial gains, but some datasets, corrected tasks, and execution frameworks were configured by Qwen, so the results should not be treated as a fair cross-vendor ranking.