擴散蒸餾只對齊最終 CFG 速度可能掩蓋分支錯誤,PDM 改為分別約束正向預測與條件方向
新研究發現,on-policy 擴散蒸餾若只匹配 classifier-free guidance 合成結果,正、負分支的誤差可能互相抵銷。Positive-Direction Matching 將兩者拆開監督,在密集到稀疏的影片控制實驗中降低模型對推論 guidance scale 的敏感度。
Archive
推論 runtime、量化、 serving、KV cache、成本與效能。
新研究發現,on-policy 擴散蒸餾若只匹配 classifier-free guidance 合成結果,正、負分支的誤差可能互相抵銷。Positive-Direction Matching 將兩者拆開監督,在密集到稀疏的影片控制實驗中降低模型對推論 guidance scale 的敏感度。
 代理工具
Baidu’s research team has released 100 long-horizon document, spreadsheet, and presentation tasks, along with human labor time, price proxies, and executable validators. The best model achieved an average score of 17.91, compared with the human baseline of 27.79, showing that cheap and fast inference does not necessarily produce deliverables that are ready to use.
 最新模型
Moonshot AI has officially released the Kimi K3 weights and technical report. The model features native vision, a one-million-token context window, and activates 16 of 896 experts for each token. The open weights finally make the company’s capability claims reproducible, but more than 1 TB of low-precision weights still put full deployment beyond ordinary workstations.
 最新模型
Laguna S 2.1 uses sliding-window attention, attention gating, and an FP8 KV cache to reduce long-context costs, targeting self-hosted agentic coding. The model comes with weights at multiple precision levels and complete evaluation trajectories, but its million-token capability, performance comparisons, and single-machine feasibility still depend heavily on the quantization format and runtime environment.
 推論系統
Researchers enabled agents to predict and pre-execute their own next tool calls during inference, replacing an external draft model with shared weights and a shared KV cache. Joint reinforcement learning raised average Hit@1 to 61.2 and 66.3 for two Qwen 4B models, respectively, though the paper has yet to quantify end-to-end speedups in real-world parallel deployments.
 AI 安全
The open-source SkillGate uses 530 rules to identify suspicious snippets before agents load skills, then sends them to an LLM for classification and isolation. Official benchmarks measured a 1.13% false-positive rate and 76.9% recall, showing that a low-cost gateway is feasible but cannot yet replace sandboxing and least privilege.
 最新模型
Shieldstral unifies content moderation as a binary question-answering task whose criteria can be specified in natural language, allowing the same model to switch standards based on the product context. The paper reports average F1 scores of 84.9% for text and 83.8% for multimodal content, but the model weights and complete inference package have not yet been released.
 開發者平台
GitHub Models will discontinue all services on July 30. Existing customers will lose access to the model catalog, Playground, inference APIs, and BYOK endpoints. Migrating to Microsoft Foundry is not simply a matter of changing URLs: teams must also revalidate identity and access, model versions, billing, and output compatibility.
 推論系統
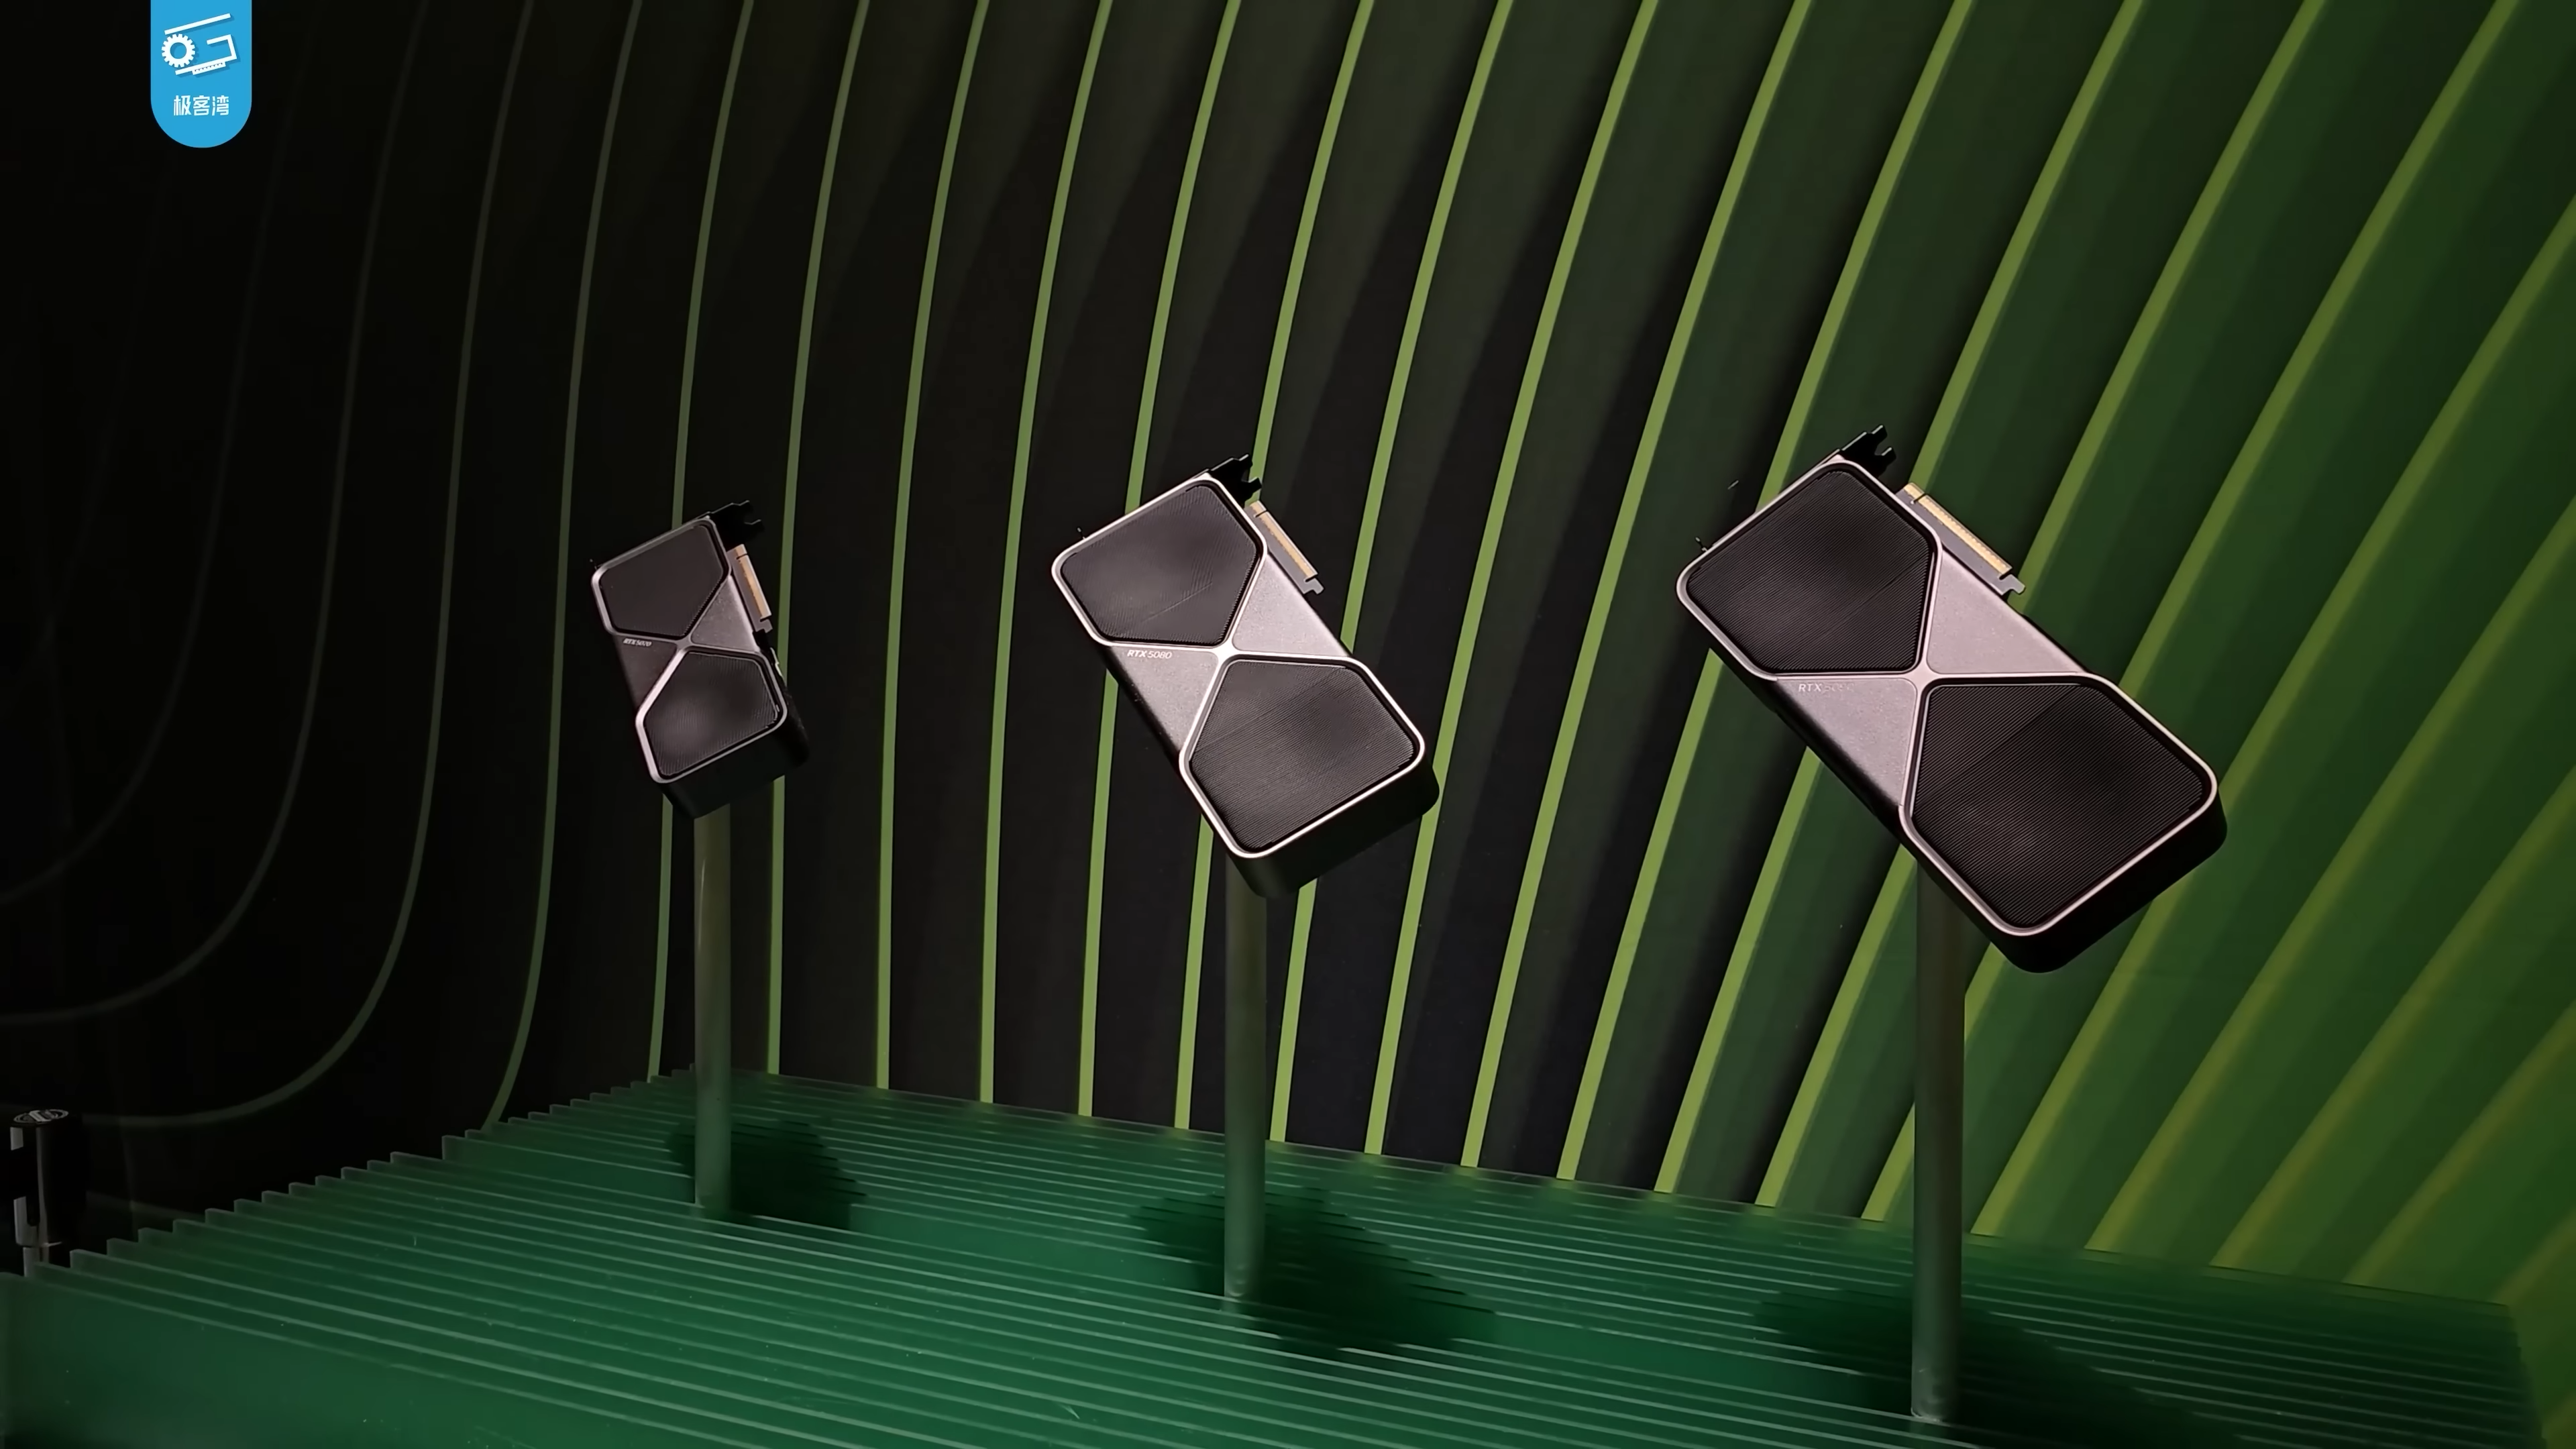
The open-source NInfer uses custom quantization, weight layouts, fused kernels, and an MTP draft path to sustain long-context decoding at about 543 tokens per second for Qwen3.6-35B-A3B on a single RTX 5090. Its speed comes from deep specialization for the model and GPU, but it currently supports only two checkpoints, lacks continuous batching, and has yet to be independently benchmarked under identical conditions.
 AI 基礎設施
MLCommons has launched Endpoints 0.7 for managed inference services, replacing twice-yearly static comparisons with automated submissions, continuous review, and interactive charts. The initial release covers five providers and three benchmarks, but cost normalization, agentic workloads, and broader participation will not arrive until version 1.0.
SpecBox 根據串流 token 推測即將使用的工具,讓沙箱啟動與模型推論重疊,並以相依圖預取後續執行環境。論文報告其 P99 端到端延遲最高改善 2.9 倍、峰值記憶體降低 45.9%,但目前仍是研究原型,尚無公開程式碼或獨立重現結果。
 硬體
CoTinyVLA distills hierarchical reasoning from a 35B teacher into a 0.9B vision-language-action model, outperforming the strongest 7B baseline across all four LIBERO-Plus test suites. Its code, training pipeline, and weights are public, but there are still no results from real robots, different hardware, or independent reproductions.