推論系統

推論 runtime、量化、 serving、KV cache、成本與效能。

推論系統

FreeToken Dynamically Splits Expert Computation Across CPU and GPU, Enabling 284B MoE Inference on a Single RTX 5090

Instead of offloading MoE experts according to fixed rules, FreeToken dynamically divides work between CPU execution and GPU caching based on measured memory and PCIe bandwidth. The authors report that an RTX 5090 can run a 284B model at 22–25 tokens per second, though testing was conducted by the development team and the full weights still require substantial system memory.
推論系統

Two-Stage Table Compression Uses 64 Visual Tokens to Find Tables, Then Reasons at Full Resolution

University of Edinburgh research shows that although low-resolution tables are unsuitable for directly reading values, they still provide enough information for a VLM to assess relevance. In long-document tests, the training-free, two-stage pipeline reduced decoder token usage by 41% and achieved an accuracy 7.1 percentage points higher than single-pass inference on all tables at full resolution.

推論系統

TensorRT Model Connect Compiles Model Checkpoints into Native C++ Bundles, but the Interface Is Not Yet Finalized

NVIDIA has released TensorRT Model Connect, which uses Python build tools to package supported Hugging Face checkpoints into TensorRT bundles loadable from C++. The project claims support for 84 model families and 221 end-to-end manifests, but it remains in nightly development, and inclusion in the support matrix does not mean every hardware configuration has been validated.

最新模型

GLM-5.3 Releases 744B MoE Weights, but Million-Token Deployment Still Requires Data-Center-Class Resources

Two weeks after launching the API, Z.ai has released the GLM-5.3 weights. The model retains GLM-5.2’s base architecture, with capability gains driven primarily by post-training for agentic coding and cybersecurity. The FP8 files still total about 756GB, and the custom license and vendor-led evaluations mean that performance, safety, and legal validation remain necessary before adoption.

機器人與具身 AI

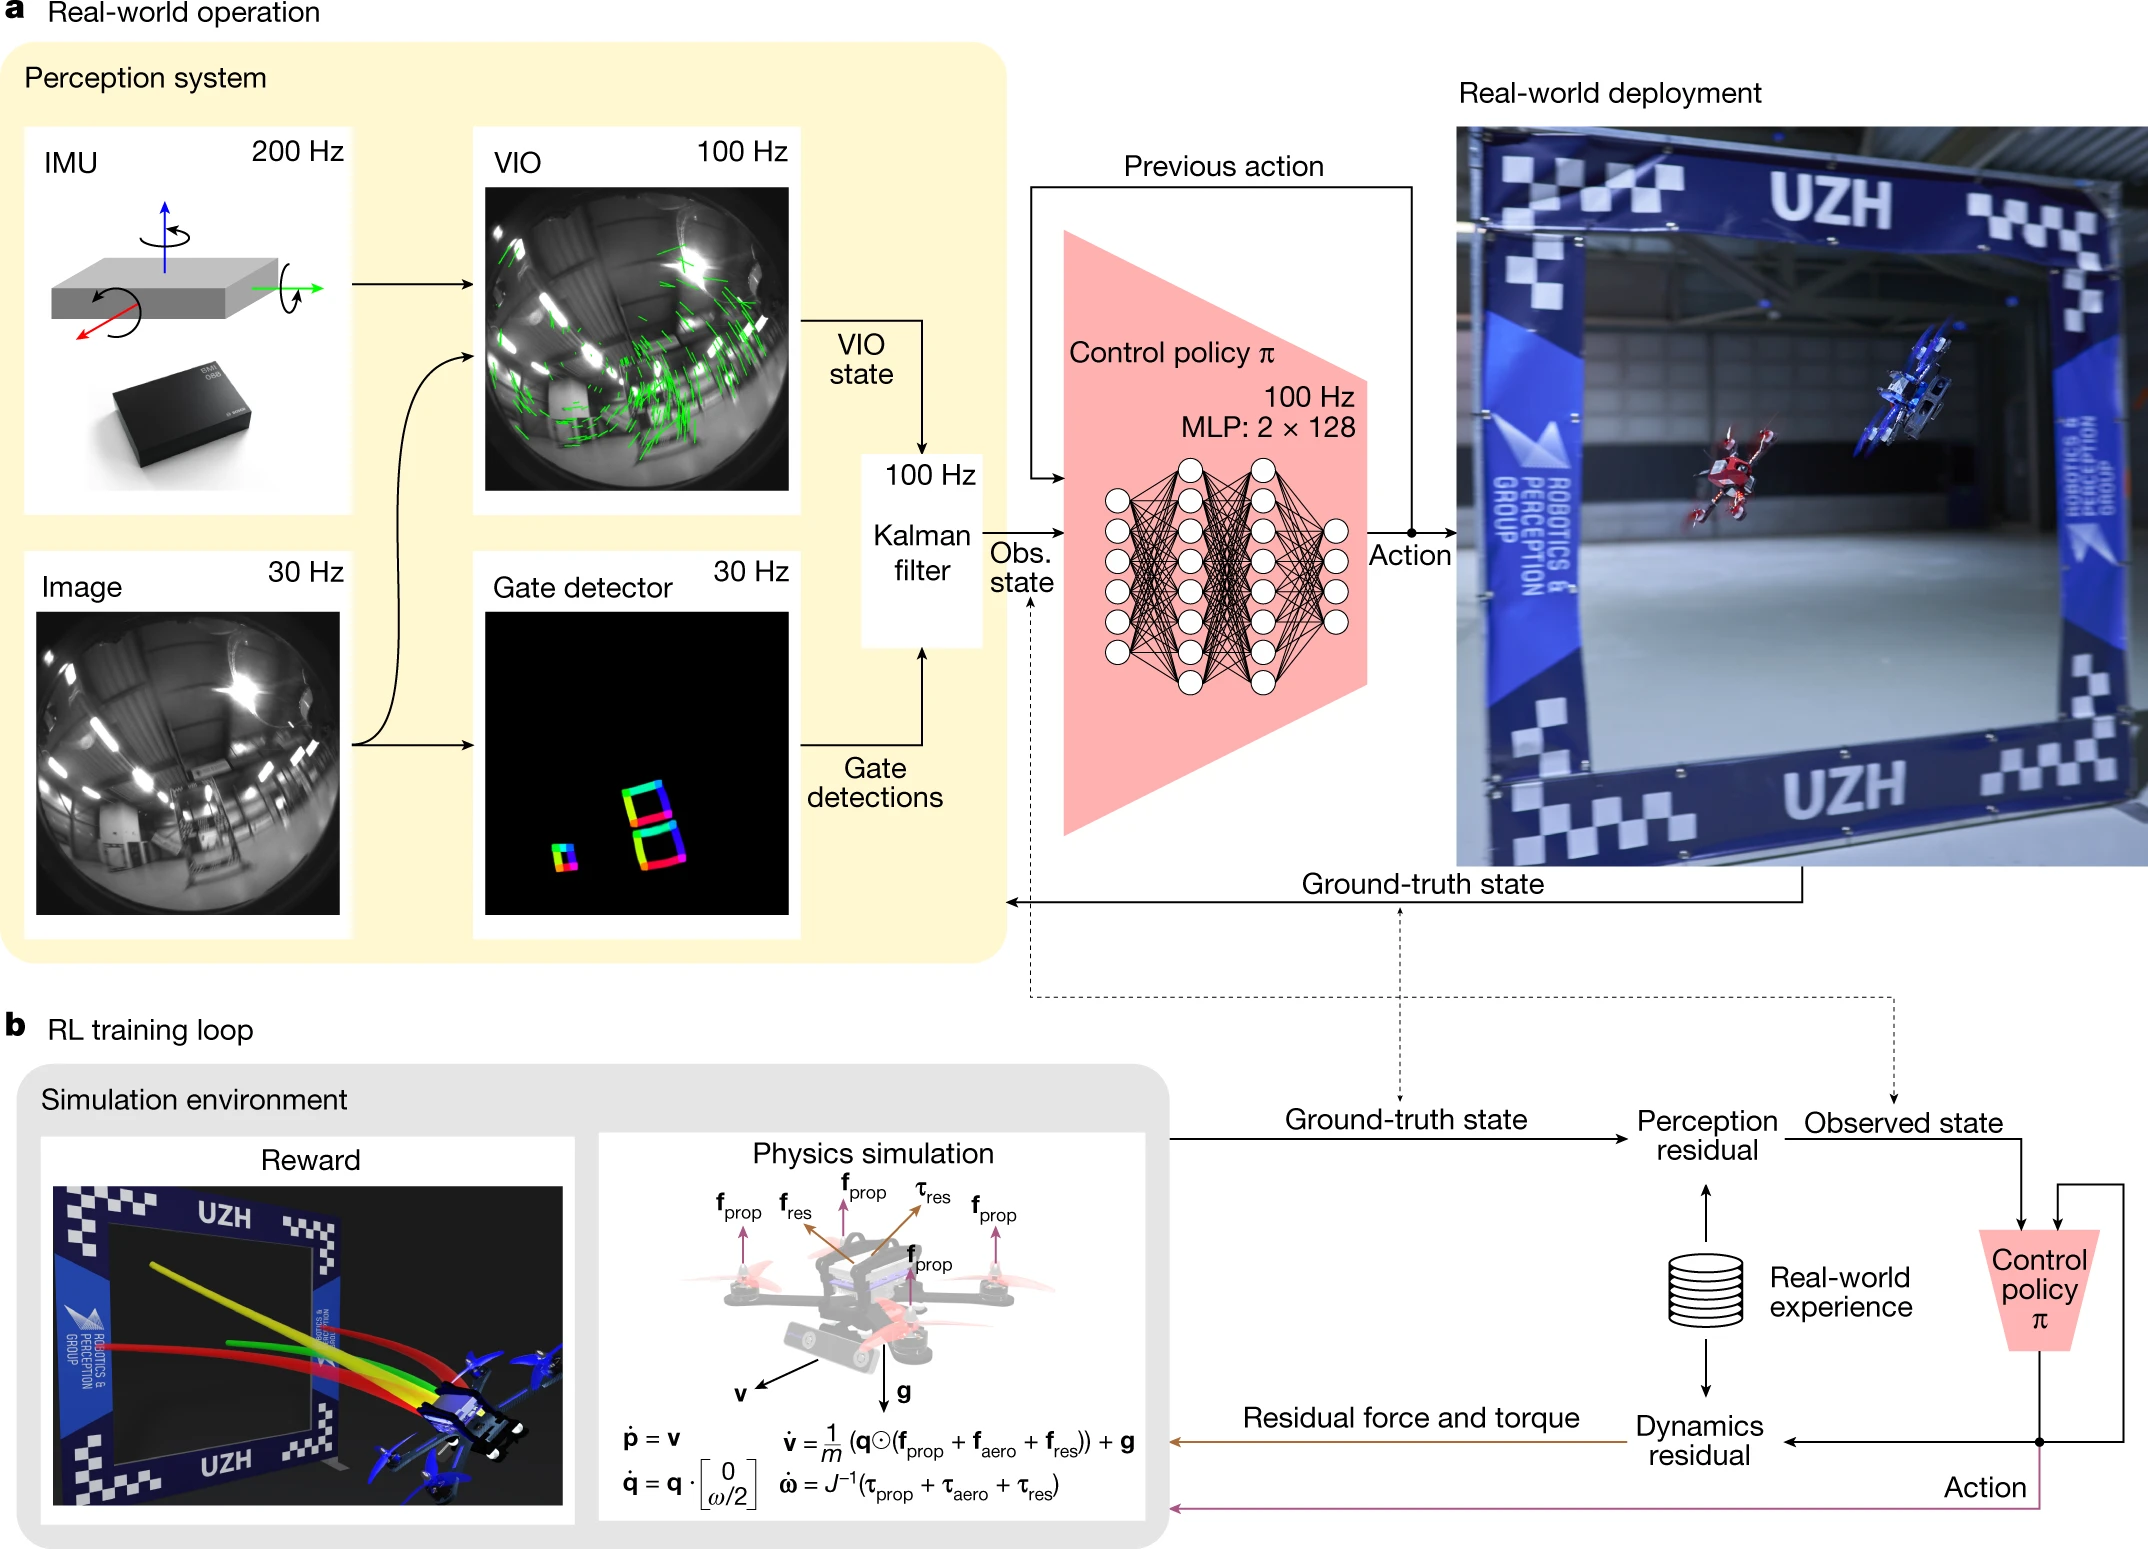
Isaac 0.5 Unifies Video Understanding and Robot Control, but Its Key Future-Perception Training Objective Remains Closed

Perceptron AI has released the weights for the 36-billion-parameter Isaac 0.5 model, along with a LeRobot integration, enabling a single sparse backbone to output language, spatial coordinates, and continuous or discrete actions. The company claims that general video can dramatically reduce the need for teleoperation data, but the figure is extrapolated from offline action loss, and the core self-supervised objective remains proprietary.

最新模型

Qwen3.8-Flash-Next Uses Block-Sparse Attention and n-gram Parameter Scaling to Preview a New Architecture for Qwen4

Alibaba has released the weights for Qwen3.8-Flash-Next, which uses Qwen Sparse Attention, Gated Residual, and 51 billion n-gram embedding parameters to reduce the computational cost of long contexts. The model natively supports 262,144 tokens, but its performance figures come primarily from official evaluations, and it is not licensed under the commonly used Apache 2.0 license.

AI 基礎設施

ROCm 10 Brings Agentic Kernel Optimization to General Availability, but the Upgrade Also Introduces ABI Breakage and Known Issues

AMD has released ROCm 10 and made ROCm.AI—integrating Hyperloom, AMD Skills, and a unified CLI—generally available. The company claims average inference and training performance gains of 3.3× and 2.4× on the same hardware, but those figures cover the entire optimization workflow and should not be interpreted as gains from simply upgrading the runtime.