GitHub Repo

GitHub 熱門專案、開源工具、框架、runtime 與重要 release。

硬體

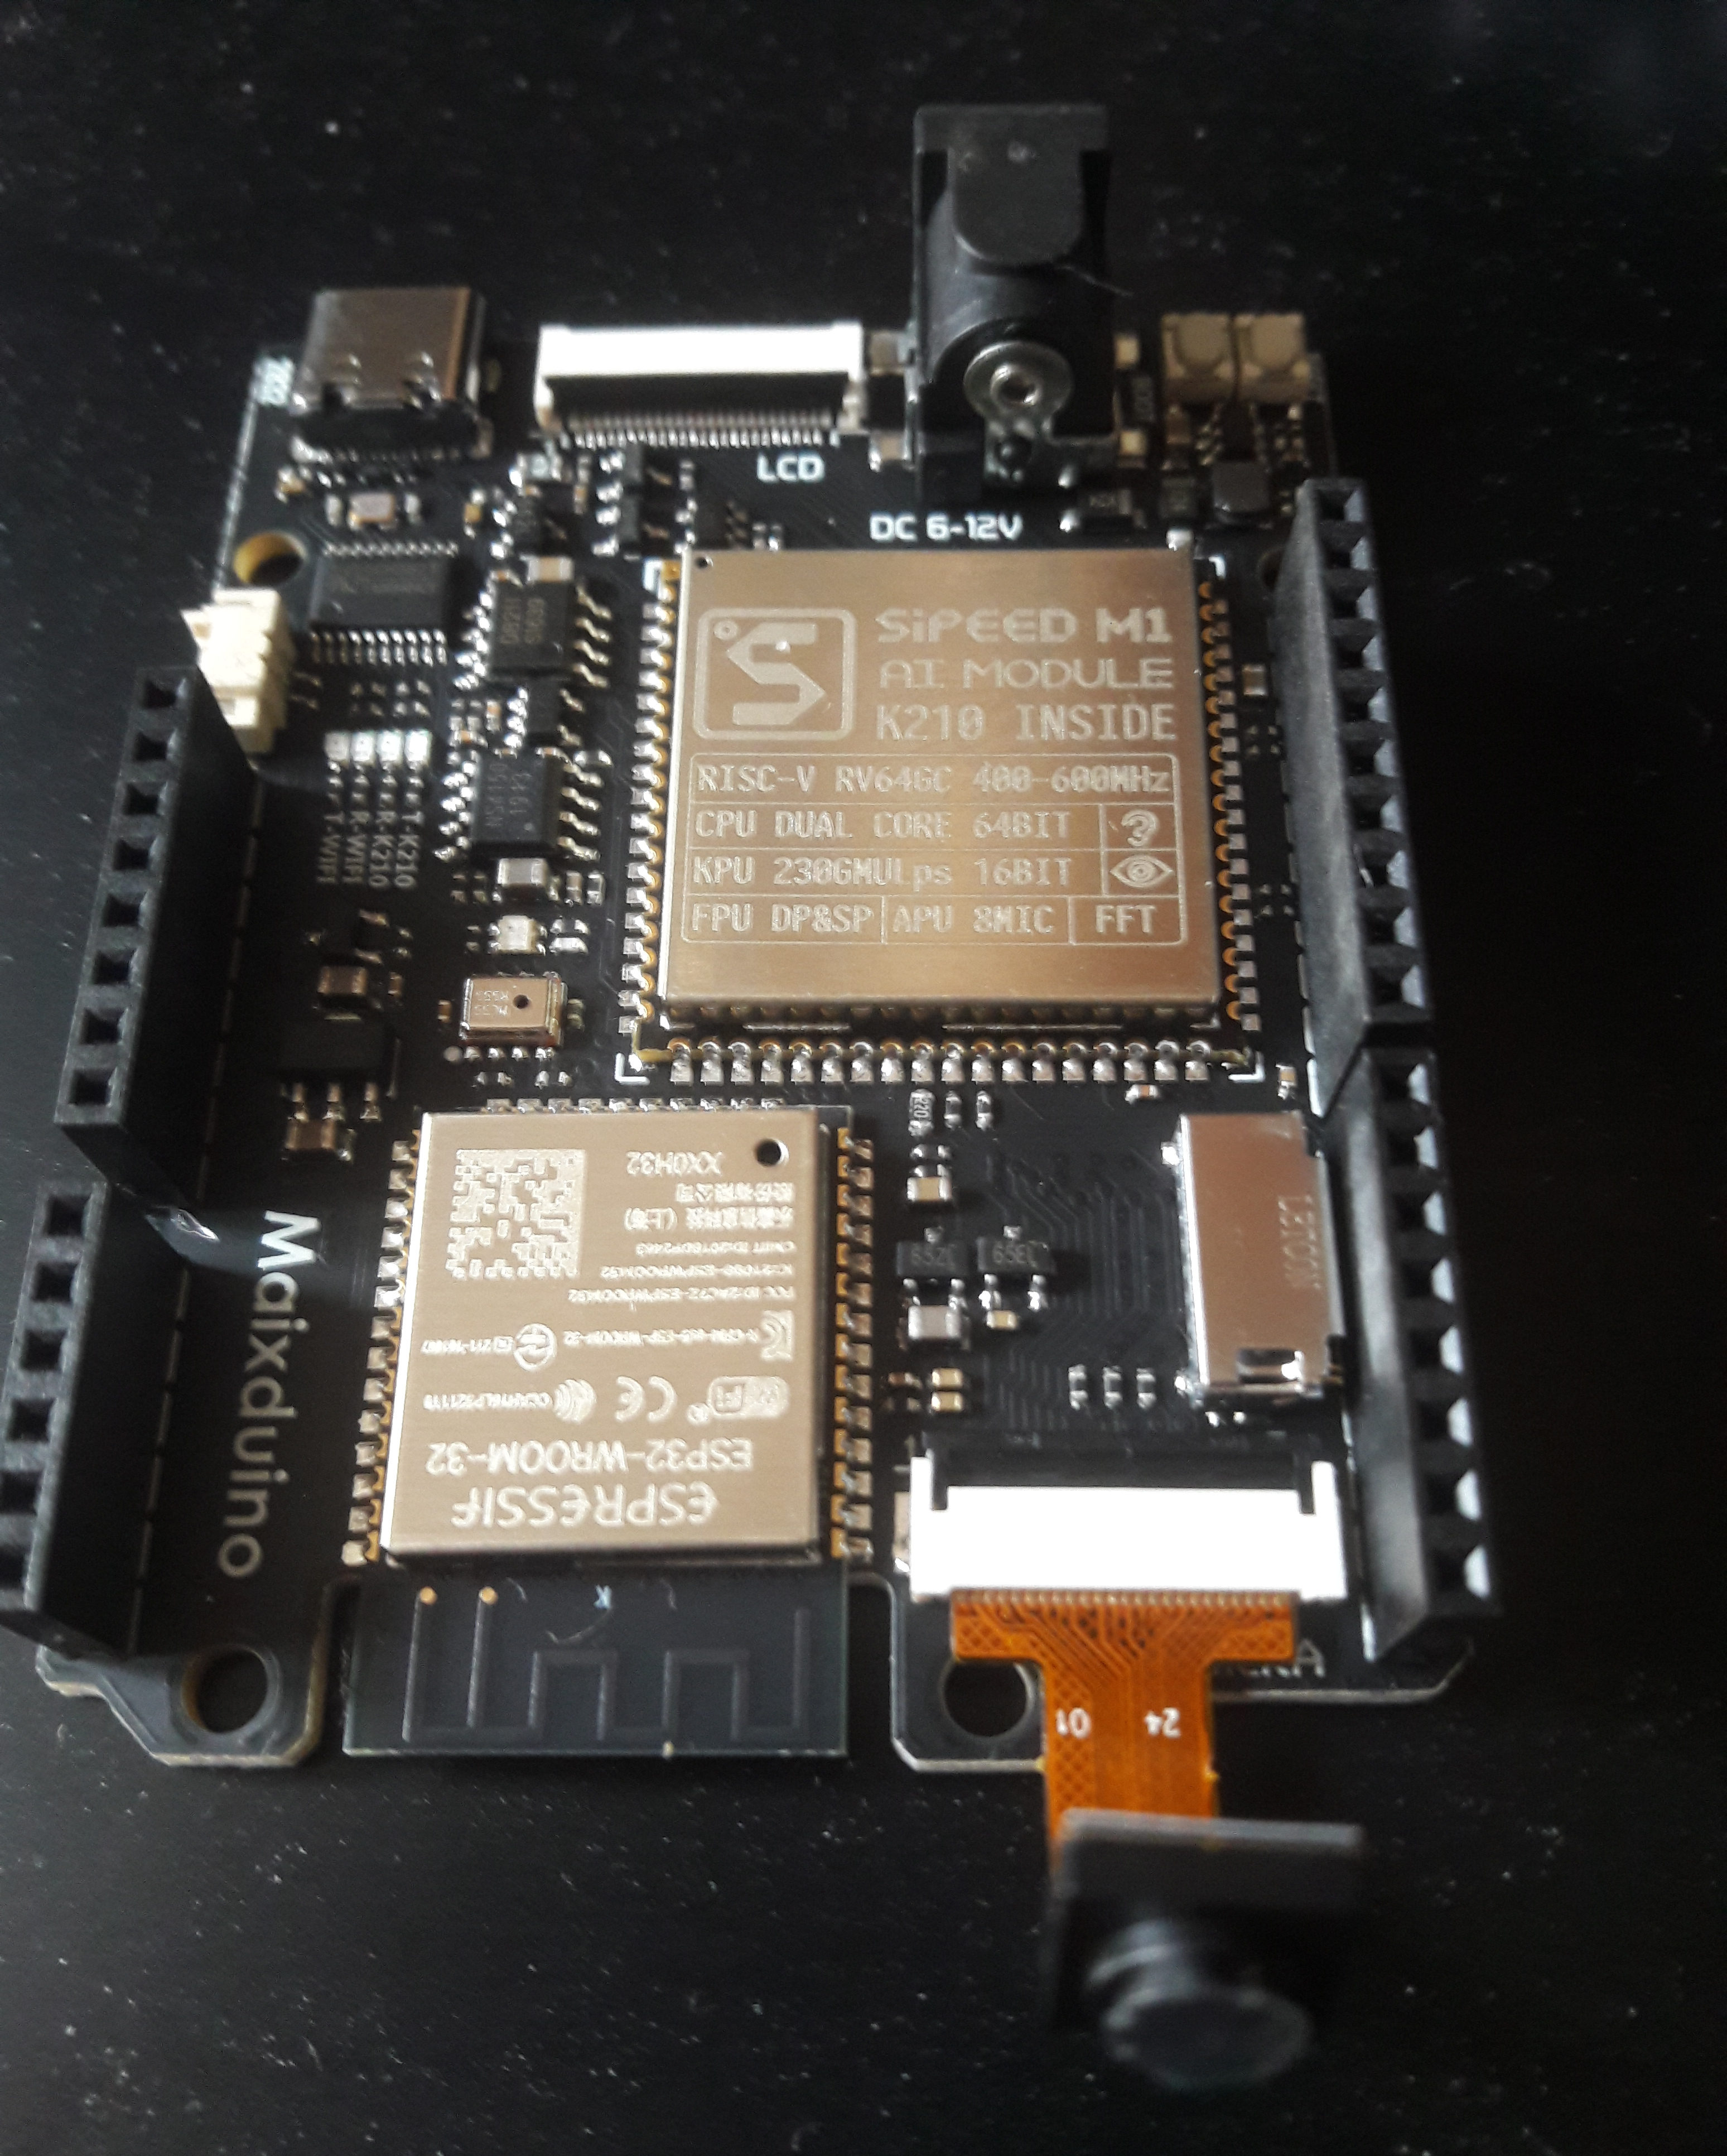
ESP32-S3 Runs a 28.9-Million-Parameter Model from 16MB Flash Using Hierarchical Embeddings, Generating About 9.5 Tokens per Second

The open-source esp32-ai project moves most parameters into memory-mapped Flash while keeping only a small Transformer core in fast memory, enabling a roughly $8 microcontroller to generate text entirely offline. The result shows that hierarchical models can be embedded in firmware, but TinyStories-level output should not be equated with general language understanding or device-control capabilities.
推論系統

HPD-Parsing Splits Document Generation into Parallel Branches, With the 1B Model Reaching Peak Throughput of 4,752 Tokens per Second

PaddlePaddle has released the 1B-parameter HPD-Parsing model, which uses a global layout branch to coordinate multiple block decoders and bypass the sequential bottleneck of generating an entire page token by token. Official tests show throughput 2.62 times that of the fastest existing comparison model, but the system currently depends on a custom vLLM package, and its peak figure cannot be directly equated with end-to-end PDF processing speed.

AI 安全

MostarGate Narrows Agent Credentials Through a Three-Layer Permission Intersection; 600-Task Dataset First Exposes Enterprise Policy Gaps

New research determines an agent’s usable permissions by intersecting role ceilings, task classification, and forbidden combinations, preventing every task from carrying full role credentials. A public dataset maps 600 enterprise tasks to 15 least-privilege categories, but the 93% improvement reflects policy revisions—not the attack-blocking rate of a deployed system.

GitHub Repo

Nanbeige4.2-3B Compresses an Agent Model With a Looped Transformer, Supporting a 256K Context With 3B Non-Embedding Parameters

Nanbeige Lab has released Nanbeige4.2-3B, pretrained from scratch on 28 trillion tokens. It repeatedly applies the same set of Transformer layers to increase computational depth without adding parameters. In official agent benchmarks, it generally outperforms the larger Qwen3.5-9B, but the results depend heavily on Nanbeige's own execution framework and still require independent reproduction.

最新模型

SGLang 0.5.16 Dynamically Adjusts Speculative Verification Length Based on Confidence and Overhauls Caching for Hybrid Architectures

The new SGLang release introduces DSpark, which changes the verification window for each round based on the draft model’s confidence, and makes UnifiedRadixTree the default cache for sliding-window, Mamba, and sparse-attention models. The release also removes several quantization backends and changes the rollout transport format, so compatibility must be checked before upgrading existing services.

最新模型

LLaDA 2.2 Lets Diffusion Models Add and Delete Tokens Mid-Generation, Targeting Iteratively Correctable Agent Loops

inclusionAI has open-sourced the 100B-class LLaDA2.2-flash, using Levenshtein Editing to let parallel decoding insert, delete, and replace content. The model outperforms the company’s own autoregressive baseline in some agent benchmarks and throughput tests, but still trails in code repair and function-calling accuracy, while serving support remains incomplete.

代理工具

FluxBench Puts Chip Agents Through the Full RTL-to-GDS Flow, With Performance Gaps of Up to 86% on the Same Model Architecture

FluxBench uses standardized prompts, tools, and technology libraries to test agents across the full flow from RTL generation through synthesis, placement and routing, and ECO, rather than evaluating only one-shot code output. The authors report that different agent frameworks using the same base model can exhibit a performance gap of 86.27%, although the commercial EDA experiments are limited in scope and the paper was previously withdrawn and resubmitted.