代理工具

Agent、MCP、coding agent、工作流自動化與評測。

代理工具

Quipu Changes Agent Writes to Knowledge Graphs from Accept-Then-Clean to Validate-Before-Commit, with Rejected Records Replayable Across Versions

Quipu places data, trust labels, rules, and decisions on dual timelines, and checks candidate state before committing agent writes. In the authors’ injected-defect test, all six defects persisted without a gate, compared with zero under Quipu, though the evidence still comes mainly from a single deterministic evaluation designed by the system’s authors.
AI 安全

CompoSkill Shows Agent Skills That Pass Individual Scans Can Still Form Risk Chains at Rates of Up to 80% When Composed

CompoSkill reframes skill security from evaluating individual packages to analyzing paths involving cross-skill data flows and side effects. Across its 1,140 test cases, the highest risk-chain formation rates for white-box and black-box attacks reached 83.3% and 80.6%, respectively, but these figures are not equivalent to real-world compromise success rates.

代理工具

Ten Thousand Agent Communities Exhibit Three Phases—Consensus, Polarization, and Apathy—With the Ising Model Predicting Opinion Evolution

A Stanford team simulated more than 10,000 communities of language-model agents and found that, over multiple rounds of communication, initially weak opinions gradually develop into consensus or polarization. Using an extended Ising model, the researchers predicted individual trajectories on previously unseen communication graphs. Political questions, however, also produced a rightward shift, showing that collaboration does not necessarily eliminate model bias.

AI 安全

JailbreakSkill Packages Jailbreaking Strategies as Evolvable Skills, Raising HarmBench ASR by Another 13.4 Percentage Points

JailbreakSkill packages prompt rewriting, failure analysis, and skill evolution behind a unified interface, enabling red-team agents to generate new procedures from unsuccessful attack trajectories. Its second stage raises the cross-model average attack success rate on AdvBench and HarmBench by a further 17.5 and 13.4 percentage points, respectively, although evaluation relies on a GPT-4o judge.

最新模型

Intern-S2-Mobius Shares FFN Memory Globally, With the 35B Model Reporting Nearly 4× End-to-End Inference Acceleration

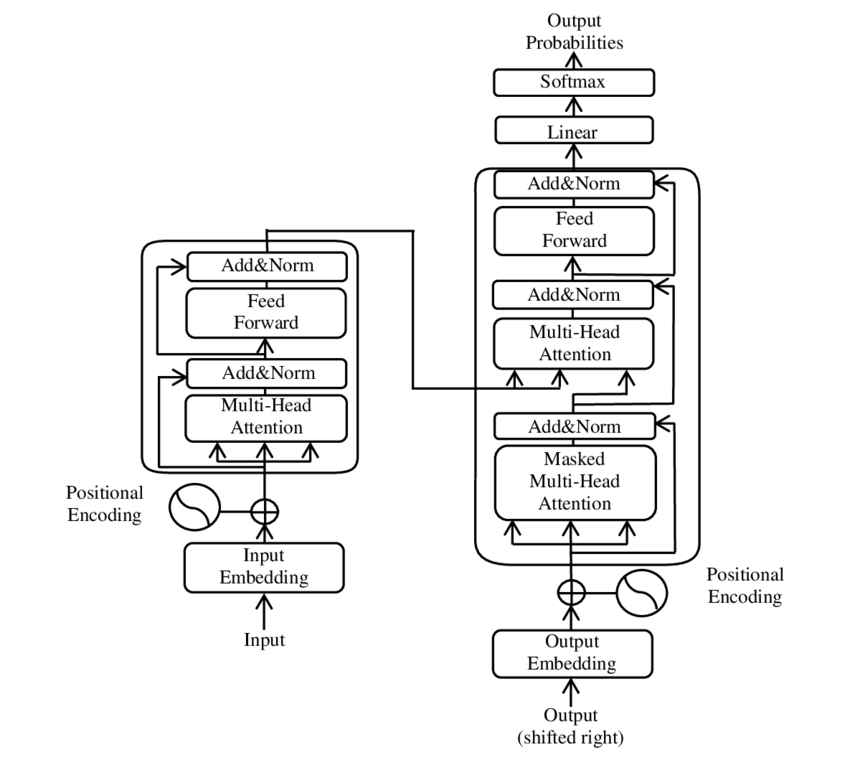
Intern-S2-Mobius separates the knowledge storage and attention-based reasoning traditionally tied to each Transformer layer, allowing multiple Reasoners to repeatedly query the same global Memory. The open weights can be loaded with LMDeploy, vLLM, or Transformers, but the nearly 4× acceleration remains a result from the official evaluation under specific conditions.