 推論系統
IOL-AI Tests Reasoning on Unreleased Linguistics Olympiad Problems: A 14B Model More Than Doubles Its Baseline Score Through Its Decoding Pipeline
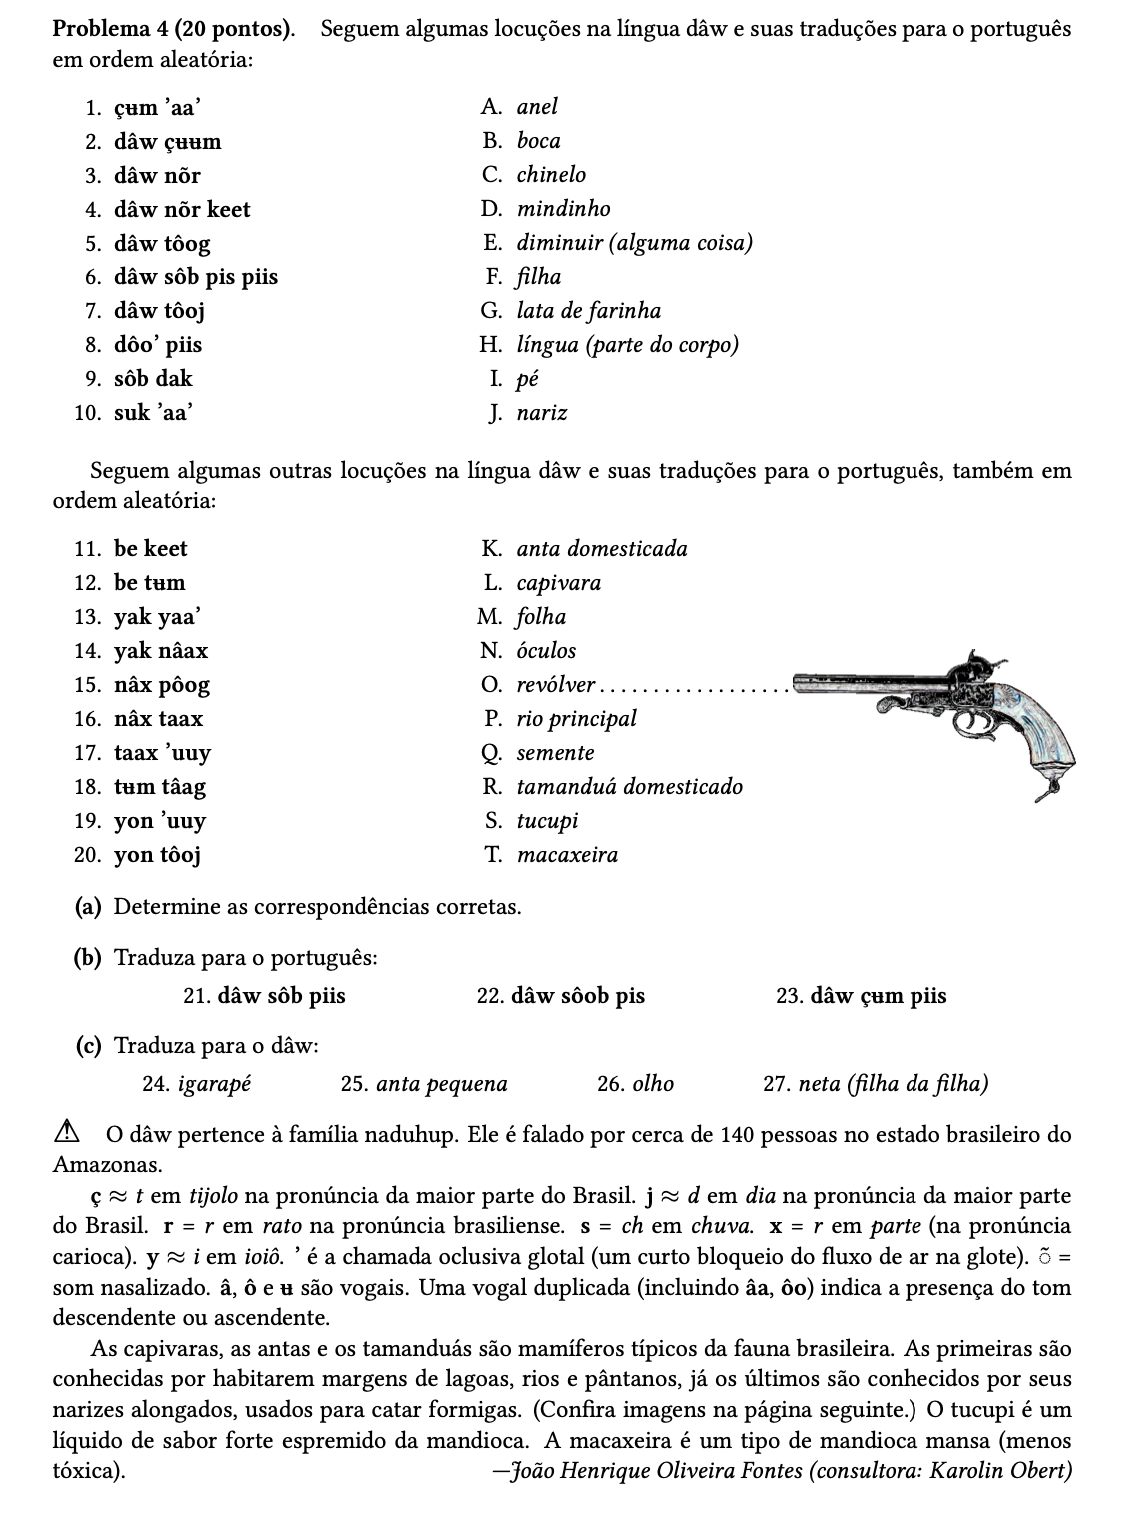
The IOL-AI Challenge requires systems to infer the rules of an unfamiliar language from a small number of examples before completing translation, transcription, and correction tasks. Under a single-T4 constraint, the best submission raised the same model’s baseline GM score from 9.40 to 19.79, but still lagged well behind closed models that reached the gold-medal threshold.