最新模型
Sarvam Opens Prism Decision Model Weights, Producing Option Probabilities in a Single Forward Pass
Sarvam released Prism on November 3, replacing fixed-choice judgments with a single forward pass and releasing its weights under the Apache 2.0 license. The company reports a 44 ms median request latency on a single B200, but Chinese-language performance and real-world serving loads still need validation.
Sarvam released Prism on November 3. Based on Sarvam 105B, the decision model takes a scenario, a question, and predefined options, then directly outputs a probability for each option. For tasks such as customer support routing and evaluating agent outcomes, the engineering benefit is skipping token-by-token answer generation and subsequent parsing. The weights are available under the Apache 2.0 license. Release announcement
Prism is fine-tuned with LoRA and uses a small scoring head to produce probabilities. Its attention design lets the scenario and question blocks attend bidirectionally, while each option can attend only to the shared scenario and itself; the options are then compared together at the answer marker. Training combines cross-entropy with label smoothing and Brier loss, with the aim of reducing overconfident errors. Options are also scored in a fixed order to reduce variation caused by input ordering. Technical overview
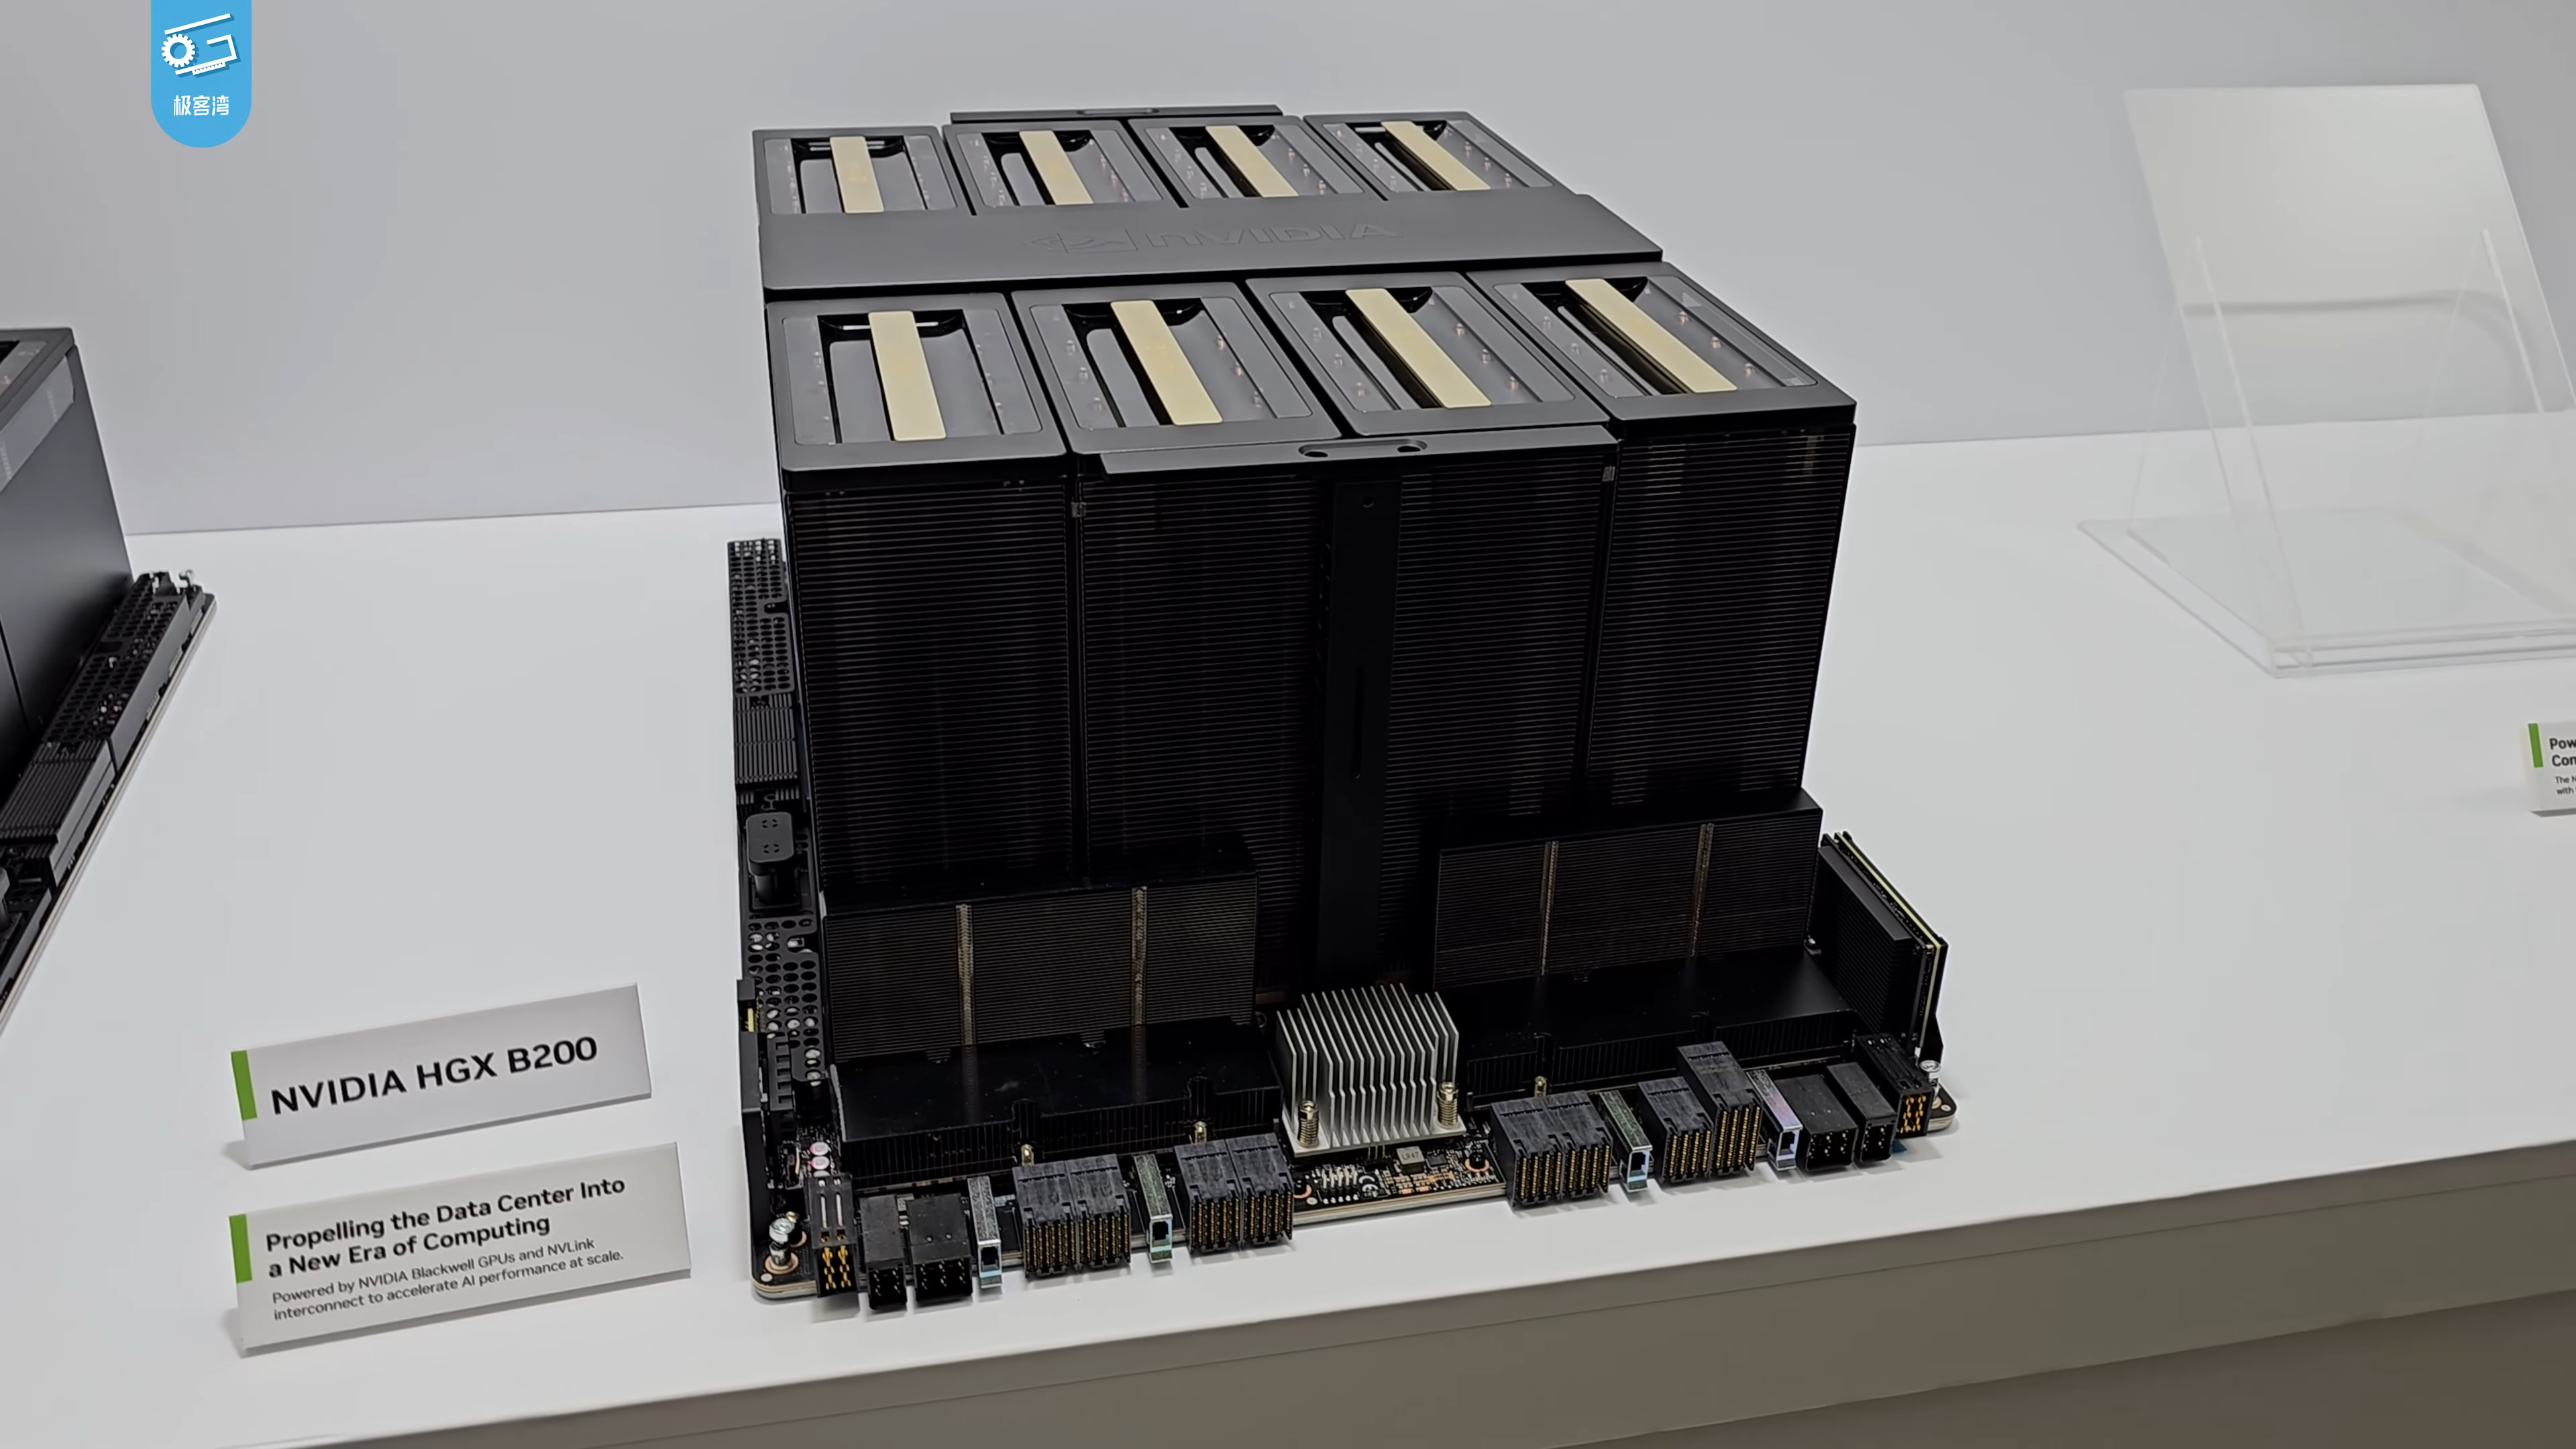
According to the official model card, after loading, a single B200 processed 1,000 public Decision Index random requests one at a time, with a median latency of 44 ms and a 95th-percentile latency of 420 ms. The gap between the two figures shows why engineering teams still need to measure performance with their own input lengths and tail-latency requirements; the median should not be treated as a service guarantee. Self-hosting requires an NVIDIA GPU with FP8 support and about 120 GB of available memory. The weights use a custom format and must be run with the supplied inference code, so they cannot be loaded directly by a general-purpose inference server. Model card
There is also a context-length difference between deployment options: the public model card lists 131,072 tokens per question, while the hosted API documentation limits each question to 32,768 tokens and uses synchronous JSON responses. The API supports single-choice, yes/no, and ordered-scale questions, making it suitable for connecting probability thresholds to automated handling or human-review workflows. Before integration, teams should confirm the limits of the self-hosted and cloud interfaces separately. API documentation
Current performance and calibration results come mainly from the development team’s tests; some comparisons use internal datasets or reconstructed metrics. The languages listed by Sarvam are primarily English and Indian languages, so equivalent accuracy in Traditional Chinese cannot be assumed. Chinese-language teams should next validate error rates against real support tickets or agent traces, including changes in option wording, confidence thresholds, and data distribution, before deciding which actions can be automated. Evaluation methodology, language coverage